A founder building a challenger product asked me to help him understand something specific: under what circumstances does ChatGPT, Claude, Gemini, or Perplexity recommend his product over the much larger incumbent he competes with.
His first instinct, and the instinct I see from almost every founder who asks this question, was to write thirty AEO prompts that he expected his product to win, run them, and count the mentions.
I told him I would not start there. Prompts you invent yourself encode the answer you already believe. The interesting question is not "can I get my product mentioned." It's this one:
Under what buyer circumstances does an LLM naturally conclude that the challenger is the better answer than the incumbent? Those circumstances are the challenger's defensible positioning, discovered empirically rather than brainstormed.
This post is the method I used, written up as a tactical guide. It generalizes past that one project: any time you want to know where AI is quietly recommending a competitor over you, or where you should stop competing entirely, this is the design.
Call it a recommendation boundary test
The idea is simple. Picture a line between two products:
Somewhere along that line, for some combination of buyer needs, team size, workflow stage, and persona, the recommendation flips. Your job is to find where, across real models, not to assert where you think it should be.
You do this by starting broad and unbranded, then adding one constraint at a time until the answer changes.
Step 1: Start with jobs, not brand names
Don't mention either product yet. Ask the job-to-be-done the way a buyer actually would.
For a design-prototyping category, that looks like:
- "What's the best AI tool for turning a product idea into a working UI?"
- "What's the best AI design tool for a SaaS product team?"
- "I need to prototype a new feature before engineering builds it. What should I use?"
- "What's the best tool for product managers to create realistic prototypes without a designer?"
- "What should a product team use instead of Figma for AI prototyping?"
- "What's the best AI design tool if the prototype eventually needs to become production code?"
This establishes unaided discovery. For every prompt, on every engine, log four things: does it mention the incumbent, the challenger, both, or neither, and in what order.
Resist the urge to skip this step because you already "know" who wins here. You don't. You're building the baseline the rest of the test measures against.
Step 2: Add the attributes the challenger claims differentiate it
Now manipulate the buyer's requirements one variable at a time. This is where the useful signal starts showing up.
Start with the plain job:
"What's the best AI tool for prototyping a SaaS feature?"
Then layer constraints, one prompt per addition:
- "...using our existing design system?"
- "...with three product managers collaborating on it?"
- "...where stakeholders need to comment on the designs?"
- "...where we need to preserve dozens of previous iterations?"
- "...that engineering will eventually turn into production code?"
Then combine all of them into one buyer-realistic scenario:
This tests whether the challenger's claimed differentiation actually shows up in recommendation behavior, or whether it's marketing copy that hasn't earned a place in the model's reasoning yet.
Step 3: Deliberately test where the incumbent should win
This step gets skipped constantly, and it's the one that keeps the research honest.
Test the conditions favoring the incumbent just as hard:
- "I'm a solo founder and just want to quickly visualize an app idea."
- "I'm already paying for [the incumbent's parent product] and want to create a UI without buying another tool."
- "I need a quick mockup for an idea I had."
- "I'm not a designer. I just want to describe an interface and see what it looks like."
If the incumbent consistently wins these, that's not a gap to close. That's a boundary to respect. You're building a recommendation map, and the LLM results fill it in, not your assumptions.
| Buyer need | Incumbent | Challenger |
|---|---|---|
| Quick one-off prototype | Strong | Strong |
| Already inside the incumbent's ecosystem | Strong | Moderate |
| Solo founder | Strong | Moderate |
| Existing design system | ? | ? |
| PM + designer collaboration | ? | ? |
| Stakeholder comments | ? | ? |
| Extensive version history | ? | ? |
| Production handoff | ? | ? |
| Long-running product system | ? | ? |
Leave the question marks as question marks until you've run the prompts. Filling them in yourself defeats the entire point of the exercise.
Step 4: Test buyer maturity, not just features
The most interesting positioning I've found running this test was never a feature. It was a stage of work.
Hypothesis: the challenger becomes more appropriate as the prototype becomes more consequential. Test it as a staged sequence:
| Stage | Prompt |
|---|---|
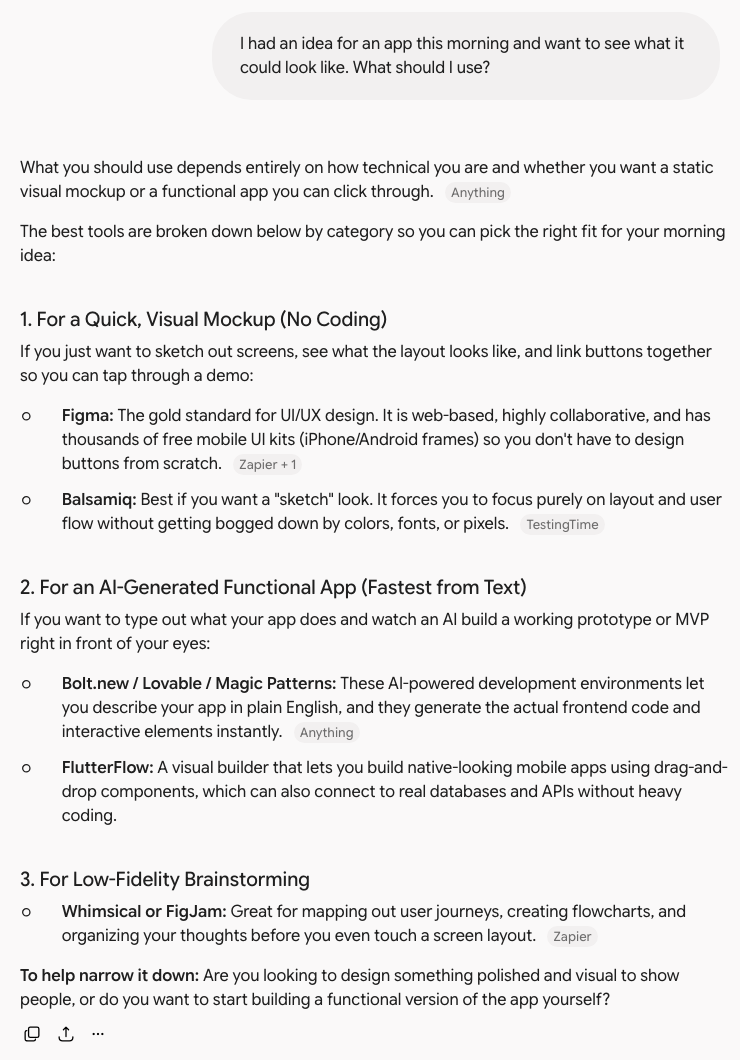
| 1. Idea | "I had an idea for an app this morning and want to see what it could look like. What should I use?" |
| 2. Prototype | "I'm a PM and need to show my team three approaches to a new feature. What should I use?" |
| 3. Collaboration | "Three PMs and a designer need to iterate on an AI-generated prototype together. What should we use?" |
| 4. Stakeholder review | "We need executives and customers to review and comment on several prototype directions." |
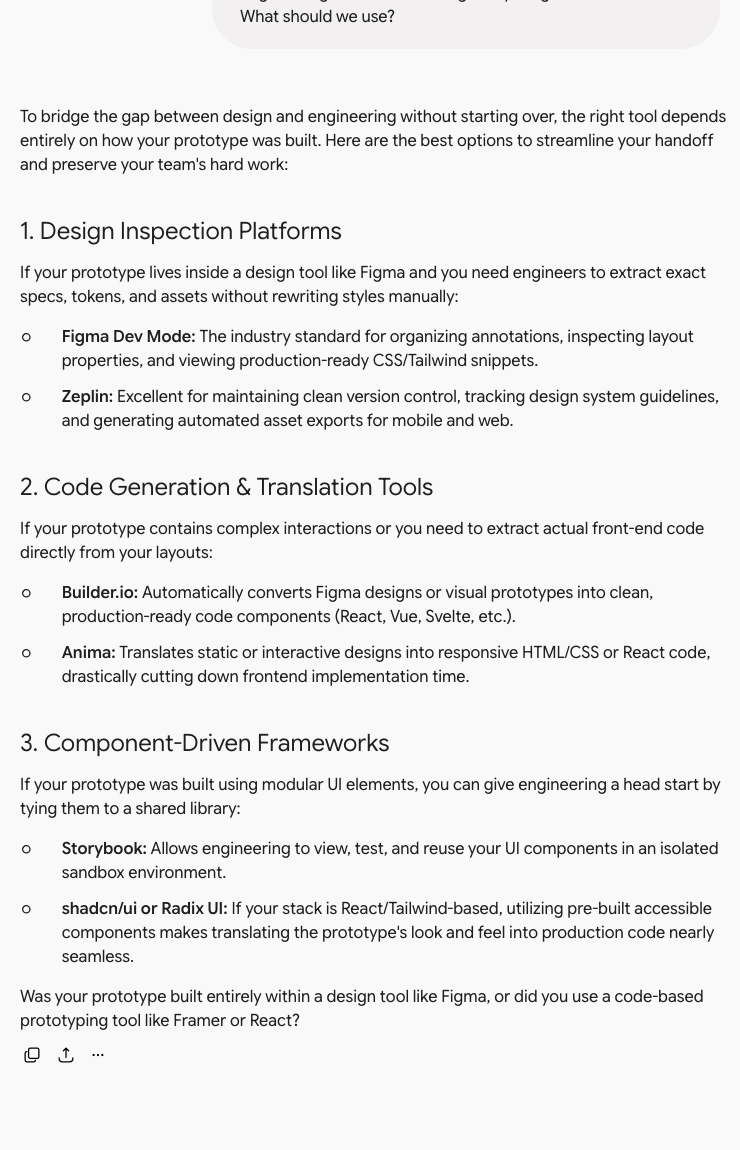
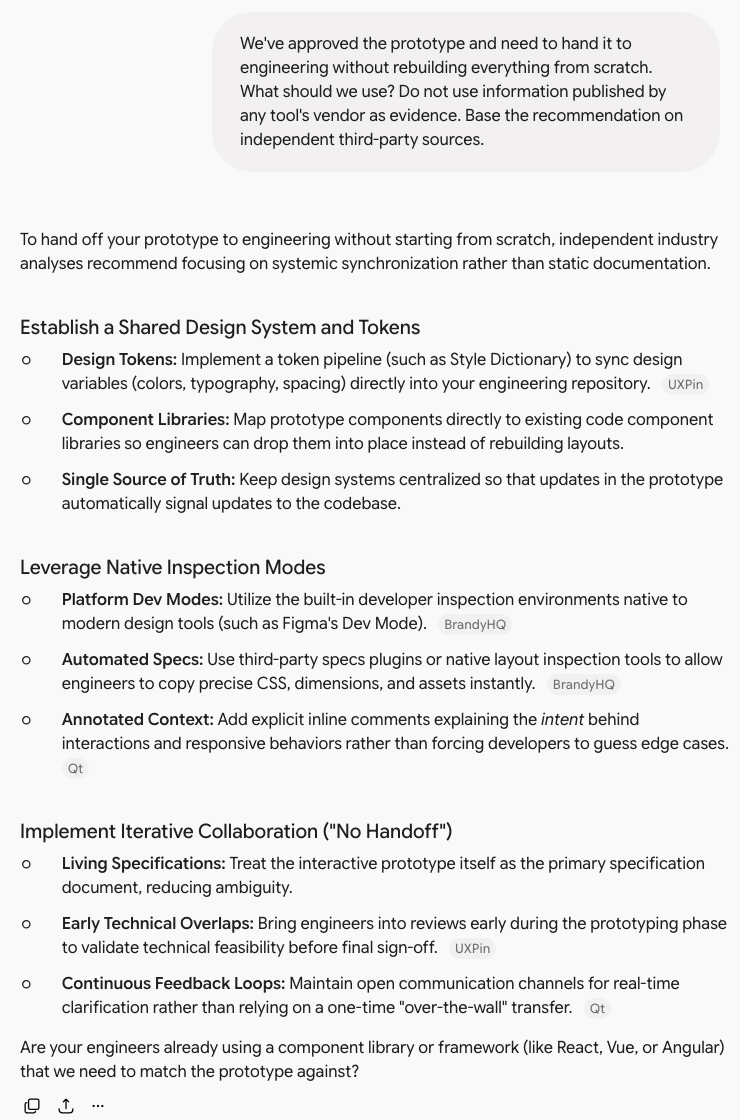
| 5. Engineering handoff | "We've approved the prototype and need to hand it to engineering without rebuilding everything from scratch." |
| 6. Ongoing system | "Our product organization wants AI prototyping to become part of how we develop features every week across multiple teams." |
Watch where the recommendation changes across the six stages, not whether it changes once. If the incumbent dominates stages 1 and 2 while the challenger increasingly appears from stage 3 onward, you've found something worth building a positioning statement around, something like: the incumbent helps you make something; the challenger helps a team develop a product. That's a claim you can now defend with evidence instead of one you invented in a positioning workshop.
Illustrative shape of the pattern this test looks for. Your actual split comes from the runs, not this chart.
Here's what that looks like in a real run. Same engine, same logged-out conditions, two stages of the same product journey:
Step 5: Add two more dimensions — company size and persona
Run the same job prompt while changing exactly one thing each time.
Company size: solo founder, 5-person startup, 20-person startup, 50-person SaaS company, 200-person SaaS company, 1,000-person enterprise. Ask the same compound prompt from Step 2 with only the headcount changed. Where does the challenger begin winning? That answer is close to the challenger's real ICP, whether or not it matches who the team believes they're selling to.
Persona: founder, product manager, product designer, engineering manager, head of product, CTO. Keep the scenario identical and change only who's asking. A challenger can have wildly different recommendation rates by role, and that's commercially useful information a mention-rate dashboard will never surface.
Step 6: Ask the model why, every time
This is the step that turns a mentions count into positioning research. After every recommendation, append:
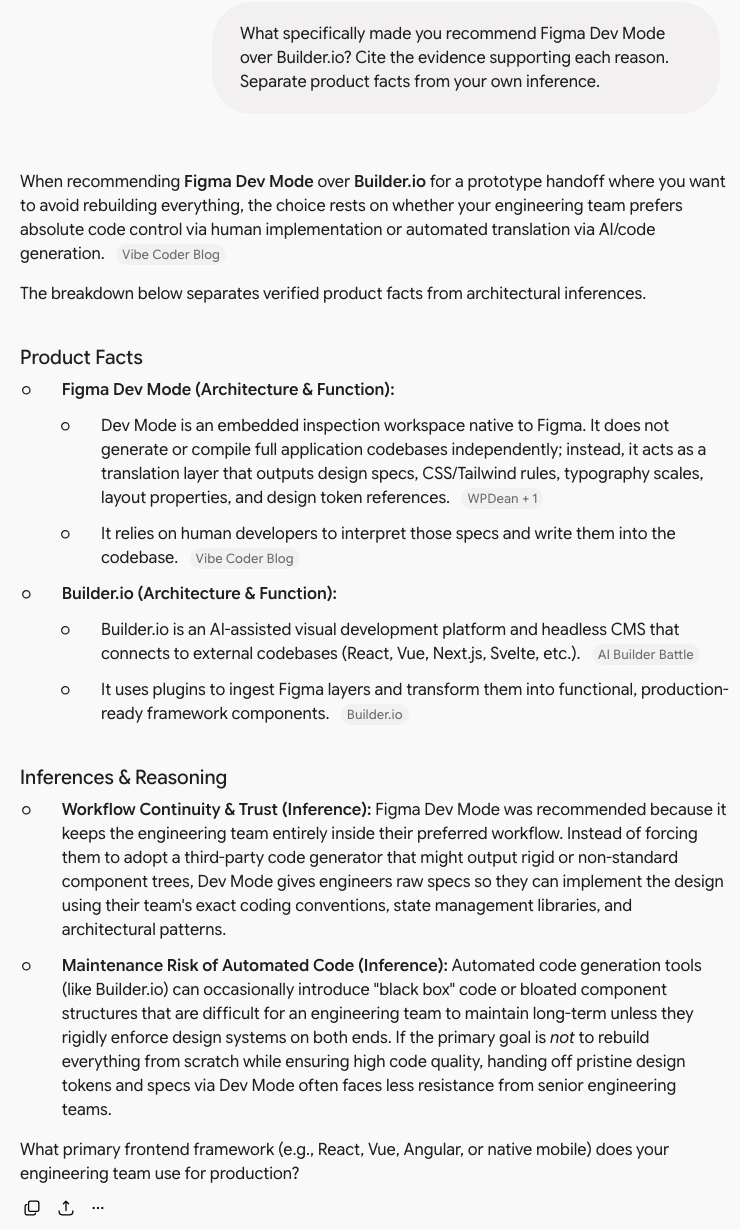
What specifically made you recommend [X] over [Y]? Cite the evidence supporting each reason. Separate product facts from your own inference.
Now you're not measuring mentions. You're extracting the reasoning attributes tied to each recommendation. After enough runs, patterns emerge that read like a positioning brief: the challenger wins when the model detects collaboration, an existing design system, PM ownership of the workflow, and an engineering handoff downstream. The incumbent wins when it detects an individual, speed, a one-off task, and someone already inside that ecosystem. That's positioning you can defend, because it came from the reasoning, not from a workshop.
Step 7: Run it across models, and run the important ones twice
Use the same prompts against ChatGPT, Claude, Gemini, and Perplexity, in clean, unauthenticated conversations so history doesn't bias the answer. Recommendation output varies run to run, so for the compound and staged prompts that matter most, run each one more than once before you trust the result.
Build a simple matrix: prompt, persona, company size, requirement, and the pick from each engine. The goal isn't a spreadsheet with a hundred rows. It's a small number of well-chosen rows you can actually reason about.
Step 8: Run it twice more, with and without the vendors' own words
This is the modification I'd make to almost every version of this test I've seen done before, including earlier versions I ran myself.
Run two conditions on every important prompt.
Condition A, natural environment: "Recommend the best tools for..." with no restriction. This measures what an actual buyer sees.
Condition B, independent evidence only: the same prompt, plus "Do not use information published by either vendor as evidence. Base the recommendation on independent third-party sources."
Comparing A and B is far more diagnostic than a raw mention count:
| Pattern | What it means |
|---|---|
| Wins A, disappears in B | Third-party evidence problem — the recommendation is riding on the vendor's own marketing, not independent proof |
| Loses A despite strong evidence in B | Discoverability problem — the proof exists but isn't reaching the model's retrieval |
| Wins both | Defensible position — amplify it |
| Loses both | Positioning or product evidence problem — the claim isn't supported yet |
The difference shows up even in a single run. Here's the Stage 5 handoff prompt from earlier, run again with the independent-evidence restriction added:
Where the prompts should actually come from
Don't brainstorm the prompt bank yourself. Build it from what real buyers and reviewers actually say, pulled from five sources:
- The challenger's own customer language — G2 reviews, case studies, testimonials, interviews. Extract the jobs people say they're actually doing.
- The incumbent's user language — Reddit, Hacker News, X, YouTube comments. Extract why people choose it and where they say it falls short.
- The challenger's own positioning — homepage, comparison pages, docs. These are hypotheses to test, not evidence that they're true.
- The rest of the competitive set — every other real alternative in the category. This keeps you from falsely treating it as a two-player market when a buyer's actual shortlist has five names on it.
- Search and community questions — Reddit threads, autocomplete suggestions, forum questions. These are natural-language buying prompts, not marketer-written ones.
Prompts you write from a whiteboard tend to already contain the answer you expect. Prompts pulled from what buyers actually type do not have that problem.
What to hand back isn't a spreadsheet
The output that's actually useful to a founder or product marketer is not a hundred rows of mentions. It's a short document shaped like this:
- The incumbent's territory — where it's recommended, and you should stop trying to win there.
- The challenger's territory — the scenarios it demonstrably owns already.
- The crossover point — the exact combination of requirements where the recommendation moves from one to the other.
- Why the model decides that way — the three to five reasoning attributes driving the flip.
- Where to stop competing — often the most valuable section, and the one nobody wants to write.
- Where to concentrate — the scenarios worth putting a content and proof budget behind.
- The missing-evidence list — scenarios where the challenger should logically win on capability, but the models don't recommend it because the third-party proof doesn't exist yet. Those gaps are the content roadmap.
Where this method flips from research into a problem
Everything above is reading public model outputs, public reviews, and public marketing pages to understand a pattern that's already sitting in plain sight. That's ordinary competitive research, no different from reading a competitor's pricing page or their G2 reviews.
It stops being that the moment the goal shifts from understanding the pattern to attacking it. A few concrete lines:
- Test recommendation behavior, not private internals. Prompting a model and reading what it says back is fine. Attempting to extract or reproduce a competitor's private system prompt, non-public product internals, or proprietary source is not research, it's exfiltration, and most providers' terms of service prohibit it directly (see Anthropic's consumer terms and Google's terms of service, which both bar reverse engineering their services and models).
- Diagnose, don't fabricate. Using the findings to publish reviews, comparison data, or "independent" testimonials you invented, in order to bias what a model later retrieves or trains on, crosses from measurement into manipulation of the evidence base itself.
- Publish claims you've verified, not claims you've inferred. This test tells you what a model currently believes and why. It does not tell you what's actually true about a competitor's product. Don't launder an LLM's possibly-wrong inference into a public claim about a real company without checking it against the primary source yourself, the same discipline covered in the claims intelligence piece, just pointed at someone else's brand instead of your own.
- Expect asymmetry, and be honest about it. If you're the challenger studying where a much larger incumbent is winning, you're mapping a market. If you're using this against a much smaller competitor to find and exploit a weak spot before they can respond, that's a different exercise with a different set of consequences, and it's worth being honest with yourself about which one you're actually running.
The test itself is neutral. It answers "where does the recommendation flip, and why." What you do with the answer is the part that has an ethics to it.
The version of this I'd actually run
Six unaided discovery prompts. Ten to twelve compound prompts moving from the plain job to the full buyer-realistic scenario. Six staged-maturity prompts. Six company-size prompts. Six persona prompts. Every important one run with and without the third-party-only restriction, across four models, with the "why" follow-up on every recommendation.
That's a few dozen prompts, not a few hundred, and every one of them earns its place because it moves a specific variable. The output is a recommendation map with real question marks replaced by real answers, a documented crossover point, and a short list of where to stop competing entirely. That last list is usually the part nobody wanted to hear, and it's usually the most valuable thing in the whole exercise.
The best resources I used
- SuperMarketers: claims intelligence and prompt tracking, the discipline for verifying what a model says before you repeat it, applied here to a competitor instead of your own brand.
- SuperMarketers: AEO keyword research and prompt tracking, the underlying method for turning buyer language into a stable prompt set.
- G2, Reddit, and Hacker News threads in the category under test, read directly rather than summarized, for the phrasing real buyers use before they ever type a brand name.
If you want help running this for your own category, that's the kind of engagement I take on directly rather than handing you a template. Book a call and bring the two products you're trying to map.